This is the story of a small Python project: a website uptime checker that took two evenings, a lot of Googling, and more mistakes than expected.
I work with data all day. SQL, dashboards, tracking implementations, the usual analyst toolkit. Python has always been adjacent to that work without ever being properly mine. I can read it. I can modify someone else’s script. But writing something from nothing, on my own, is a different muscle.
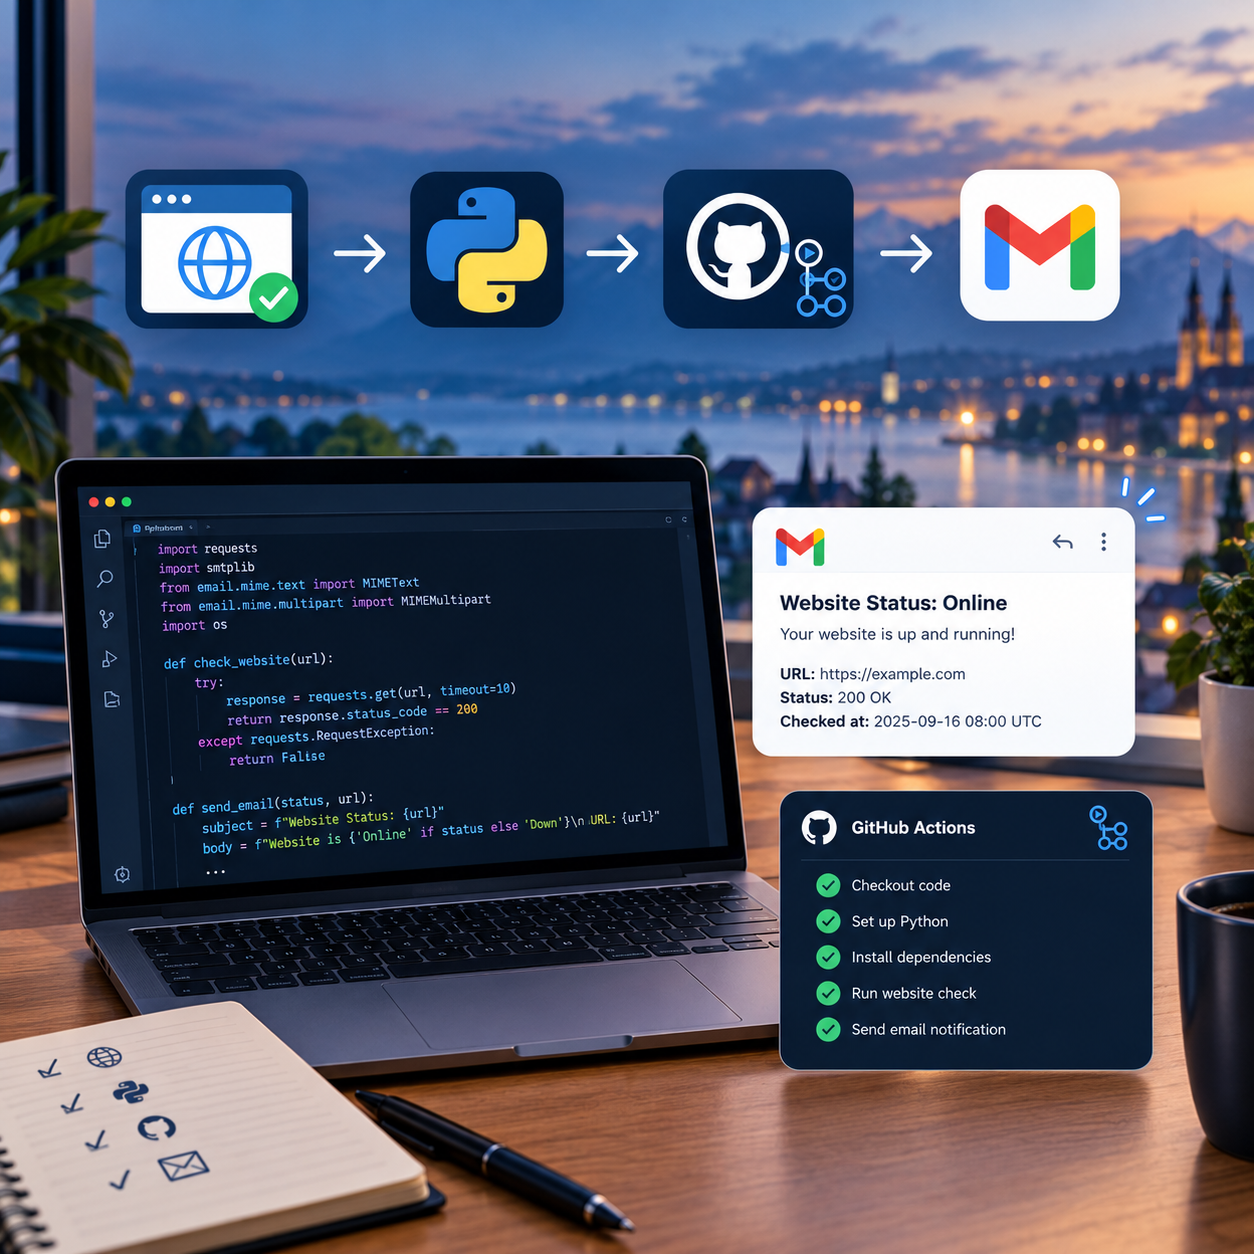
So I’ve been building small things in the evenings. Last weekend it was a website uptime checker: a script that pings my personal site, reads the status code, and emails it to me on a schedule.
This Python project took two evenings. Should have been one. Here’s what actually happened, including the parts where I got annoyed and wanted to stop.
Why this Python project
My site runs on WordPress. If it goes down on a Tuesday afternoon while I’m in meetings, I find out on Thursday when someone mentions it. Not great.
I know UptimeRobot exists. I know I could have this solved in ten minutes with a free account. But the point wasn’t monitoring my site, it was learning how a scheduled job works end to end, which is the real value of a small Python project like this one. Fetch something, do something with it, run it automatically somewhere that isn’t my laptop. That pattern shows up everywhere in analytics work, and I wanted to build it once with my own hands.
The first four lines took me twenty minutes
import requests

url = "https://yoursite.com/"
r = requests.get(url, timeout=5)
print(r.status_code)
That’s it. That’s the core of the whole thing.
But I printed the wrong thing three times before I got there. First print(r.text), which dumped the entire HTML of my homepage into the terminal. Hundreds of lines. Then print(r), which gave me <Response [200]> and felt like an answer but isn’t one. You can’t compare that to anything. It’s a label for humans.
r.status_code is the actual number. 200.
What I was missing conceptually: r is an object holding a lot of things at once. The page content, the headers, the timing, the status code. The dot reaches inside. Printing the object itself just asks it to describe itself in one line.
That sounds obvious written down. It wasn’t obvious at 9pm on a Friday.
Useful trick I picked up: type(r) tells you what class you’re dealing with, and that gives you something specific to search for. “requests Response object attributes” gets you the right docs page. Searching “python get website status” gets you fifty blog posts with fifty different approaches.
Docs: requests quickstart
The status code thing I got wrong
My first instinct: check if the code is 404, and if so, email me.
That’s wrong and it took a conversation to understand why. A dead WordPress site basically never returns 404. It returns 500, or 502, or it returns nothing at all because the server stopped answering or the domain didn’t resolve. In that last case there’s no status code to check, because there’s no response object at all. Your script just crashes.
So the better framing is: define what up looks like, which is a small set, and treat everything else as down.
I also skipped proper error handling entirely on the first pass. I know that’s a gap. I’ll come back to it. Trying to learn exception handling while also fighting SMTP was making me want to close the laptop.
The email part, where I lost an hour
I copied the official Python docs example for smtplib and it didn’t work. The example uses smtplib.SMTP('localhost'), which assumes there’s a mail server running on your machine. There isn’t. There never was.
I also had a version that connected to Gmail, logged in successfully, printed nothing, and sent nothing. Because I’d never written the line that actually sends. Connecting and sending are two separate steps and I’d only written one.
What eventually worked:
import smtplib

subject = "Website Status"
message = f"Your website status code is {r.status_code}"
text = f"Subject: {subject}\n\n{message}"

server = smtplib.SMTP('smtp.gmail.com', 587)
server.starttls()
server.login(sender_email, password)
server.sendmail(sender_email, receiver_email, text)
Two things worth knowing:
The \n\n between subject and body is not optional. Two newlines. Get it wrong and your subject line ends up inside the message body. Email headers come first, blank line, then content.
And you can’t use your Google password. You need an App Password from Google Account → Security. Sixteen characters, displayed in four groups of four, and you need to strip the spaces out.
I got the email working after watching this video. Typed it out myself rather than copy-pasting, which I think matters. I felt slightly like a fraud for needing the video. I’ve decided that’s a stupid thing to feel. Watching someone do a thing and then doing it yourself is how people have learned skills forever.
The Python project bug I’d probably write again
def check_site(url):
    url = "https://yoursite.com/"     # ← this line is the bug
    r = requests.get(url)
    return f"Status: {r.status_code}"
The function takes a URL. Then immediately throws it away and uses a hardcoded one. You can pass it any address in the world and it will always check my site.
Nobody spots this when they write it. It even works, which is the worst part.
Scheduling it on GitHub Actions
This is the bit that made the Python project feel real. The script now runs on GitHub’s computers whether my laptop is open or not.
Used this video as the starting point.
The mental model that helped: every run, GitHub rents you a completely blank Ubuntu machine for a few seconds. It copies your repo onto it, installs Python, installs your packages, runs your script, then destroys the machine. Nothing carries over between runs. That’s why pip install requests has to be a step in the config. The machine has never heard of your project.
The config file is YAML and lives at .github/workflows/yourfile.yml.
Things that cost me time:
I put the file in github/workflows/ without the leading dot. GitHub didn’t find it. The Actions tab just showed me template suggestions and I couldn’t work out why. The dot is not decorative.
I didn’t add workflow_dispatch: to the triggers at first, which means there’s no manual Run button and you’re waiting for the schedule to find out if anything works. Add it first, always. Debugging on a cron is miserable.
And my first actual run failed with 535 Username and Password not accepted. Turned out I’d written the workflow to pass a secret called EMAIL_PASSWORD but never actually created that secret in the repo settings. The script got None as the password and Gmail rejected it, which looks identical to a wrong password.
Secrets live in repo Settings → Secrets and variables → Actions. They get injected as environment variables at runtime, so the password never sits in your code.
What this Python project actually taught me
Failing at step five of six is progress. When that run failed with the Gmail error, my first reaction was frustration. But four steps had passed. The machine spun up, Python installed, my script ran, it reached Gmail’s front door. Only the last thing was wrong. Twenty minutes earlier GitHub couldn’t even find my config file.
Read tracebacks from the bottom. The last line is the error. The lines above are the path that got there. I spent a while staring at the top of tracebacks wondering what smtplib.py line 753 had to do with me.
Nobody writes YAML from memory. I asked about this and got told, correctly, that people copy an existing workflow and edit two lines. What’s worth knowing is the shape: on for when, jobs for what, steps for the ordered list. The rest you look up every time.
Small steps beat big ones when you’re stuck. My worst stretch was a file with four half-finished ideas in it. A loop I’d added, a function I’d abandoned, two different approaches to error handling. Deleting the whole thing and rebuilding in four-line increments was the only thing that unstuck me. Painful to do, obviously right in hindsight.
On using AI to learn
I used Claude heavily through this Python project, and I want to be honest about how that went, because I don’t think it’s simple.
When I asked for answers, I got answers, and I learned very little. When I asked what to search for, and what concept I was missing, and why my approach was wrong, it was genuinely good. At one point I asked for a prompt I could give another model that would force it to give me documentation links instead of code. That worked well and I’d recommend it.
Where it fell down: I got long, thorough explanations when I was tired and wanted one sentence. That’s partly on me for not saying so earlier. When I eventually said “you’re too fluffy, just tell me what to search,” the answers got much more useful.
The thing I’d tell anyone learning this way: AI is excellent at unsticking you and terrible at building your intuition if you let it do the work. The moment you paste something you can’t explain, you’ve skipped the learning and kept the output.
What’s next
The error handling I skipped. Right now if my site is genuinely unreachable, the script crashes instead of emailing me, which is precisely backwards for a monitoring tool.
Then: only email me when something changes. A daily email saying “200, all fine” is an email I’ll start ignoring within a week. Silence when healthy, noise when broken. That needs the script to remember the previous result, which on a machine that gets destroyed every run is a genuinely interesting problem.
Two evenings, one working thing, and a much better sense of why the tools are shaped the way they are. Worth it.
It is a small addition to a growing pile of weekend builds, including Amir, the local-first AI assistant I am building in Python. Every Python project like this one teaches me something the tutorials skip.